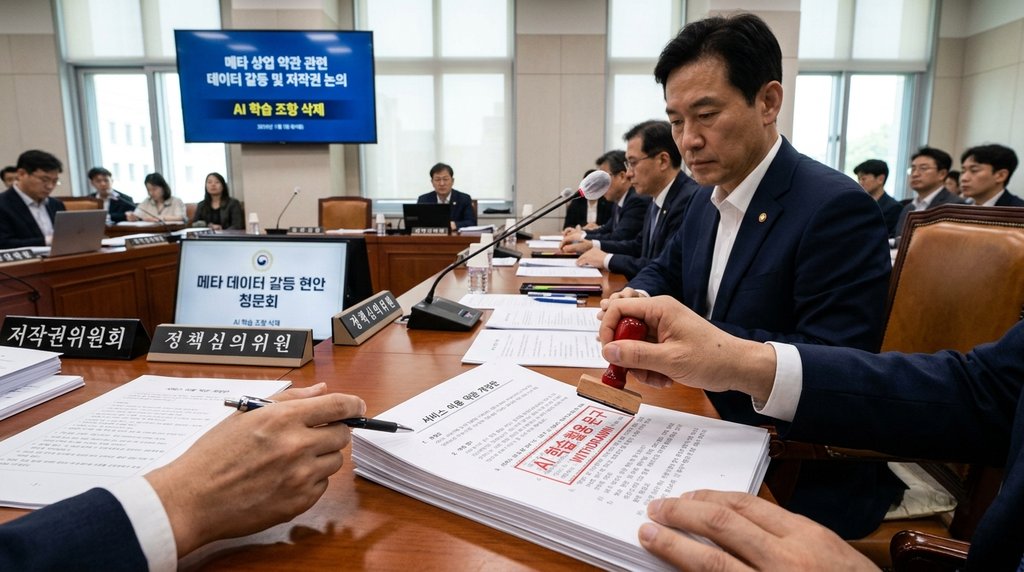
Meta has removed controversial language from its revised commercial terms of service that would have permitted the company to scrape content from external partner websites to train its artificial intelligence models. The proposed revision, originally slated to take effect on October 30, 2026, sparked widespread outrage across the media and legal sectors over fears that Meta was attempting to absorb intellectual property from third-party sites without explicit consent. In response to mounting criticism, Meta updated the commercial terms to eliminate the word train entirely, restricting data usage exclusively to the development, improvement, research, and maintenance of advertising and commercial products. Meta communications vice president Andy Stone and spokesperson Daniel Roberts maintained that the clause aimed to verify external product information to improve ad recommendations rather than scrape news websites, adding that existing web crawling policies remain intact.
Controversy mounted after media outlet Nieman Lab first reported that the terms were structured to allow Meta automated tools to scrape domains associated with Meta business accounts. Because avoiding the collection required publishers to close their accounts entirely, media organizations relying on the platform for audience distribution faced an ultimatum that effectively forced them to surrender core intellectual assets. Legal and media representatives immediately warned of grave structural risks. Cornell Law School professor James Grimmelmann characterized the provision as an aggressive poison pill capable of funneling journalistic work into systems designed to compete directly against newsrooms. Danielle Coffey, chief executive officer of the News/Media Alliance, condemned the move as an unlawful abuse of market power, emphasizing that holding audience access hostage to seize external copyright assets sets a dangerous precedent, especially given concerns that private commercial contracts might legally supersede established web crawling standards such as the robots exclusion protocol.
Meta retreat underscores the mounting regulatory and legal challenges technology giants face as they seek high-quality data to fuel frontier AI models. Over the coming six months, media organizations and enterprise partners are expected to launch comprehensive reviews of commercial agreements with platform providers to uncover hidden data-harvesting provisions. As regulatory scrutiny and public pressure close contractual loopholes designed to circumvent conventional crawling restrictions, big tech companies will face heightened demands to implement transparent licensing agreements and strictly separate commercial advertising tools from AI training pipelines.