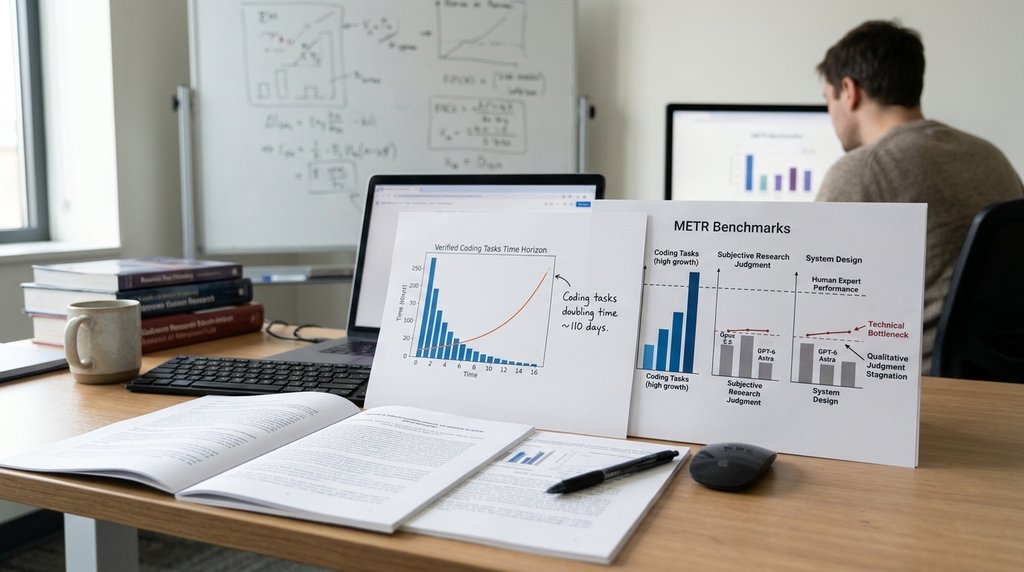
Frontier artificial intelligence systems are advancing along an exponential trajectory in deterministic engineering tasks while lagging behind human baselines on open-ended research problems, according to an evaluation report released on November 20, 2026, by the nonprofit METR. Analyzing benchmark results that incorporate leading systems such as Opus 5.5 and GPT-6 Astra, METR found that the human-equivalent time horizon of verifiable tasks models can solve with a 50 percent success rate is now doubling approximately every 110 days, down from roughly 210 days in evaluations conducted between 2019 and 2024. The benchmark pool has expanded significantly, growing from an initial 170 tasks in TH1 to 228 in TH1.1, and further integrating 36 advanced tasks across 12 product suites in TH2. These metrics demonstrate that models are rapidly scaling their capabilities in environments where solutions can be automatically scored through unit tests and deterministic rules.
However, this rapid doubling cadence collapsed entirely when models encountered tasks requiring subjective human judgment. In a newly introduced evaluation task requiring the design of an artificial intelligence evaluation framework for real-world use, not a single tested model produced an output that METR staff considered practically useful. Even Opus 5.5, regarded as possessing top-tier reasoning capabilities, barely managed to score just above the baseline. METR researcher Matt Putz explained that tasks requiring subjective judgment or lacking simple verification are inherently far more challenging to analyze and measure systematically. Computer scientist Sayash Kapoor also observed that the research intuition required to select promising questions, hypotheses, and experimental designs serves as a decisive bottleneck obstructing the full automation of scientific research.
This structural divergence stems directly from how models are trained using reinforcement learning. In domains such as code optimization and mathematics, immediate and unambiguous reward signals allow models to map exponential improvements and rapidly match elite human engineers. Conversely, long-term qualitative domains like research design and hypothesis formulation lack well-defined reward functions, preventing models from establishing stable learning curves. For technology organizations and enterprise infrastructure teams, these findings highlight the need to separate investments based on workflow characteristics. While automated pipelines for software development and scripting can directly leverage the roughly 110-day doubling cycle, deploying costly frontier models across R and D pipelines risks disappointing outcomes without prior infrastructure to verify qualitative outputs.