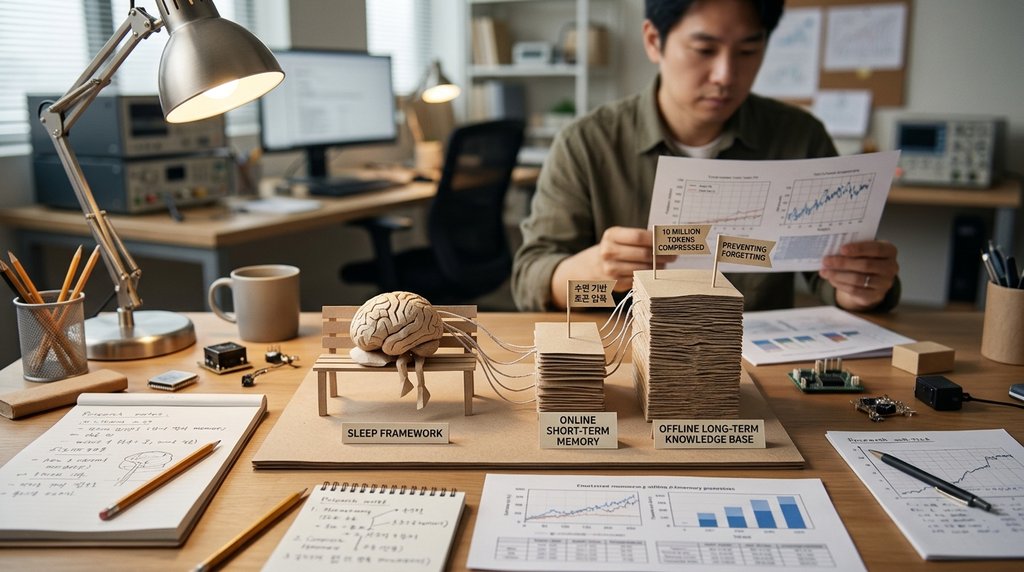
Google Research has unveiled a novel architecture designed to solve one of the most stubborn hurdles in machine learning: catastrophic forgetting during continual model updates. Announced by a research team led by Ali Behrouz and Vice President and Fellow Vahab Mirrokni, the Sleep framework mimics the biological mechanisms of the human brain, where short-term memories gathered during waking hours are transferred from the hippocampus to the cerebral cortex during rest. In this system, conversational and operational context collected during active deployment is initially stored in high-frequency temporary parameters. During an offline sleep phase, these data points are distilled into pre-allocated, low-frequency mixture-of-experts parameter blocks, consolidating the new knowledge directly into permanent weights before the temporary parameters are cleared.
Traditional approaches to model updates have forced engineering teams to choose between constant fine-tuning, which often collapses performance on previously mastered benchmarks, and external retrieval-augmented generation. While retrieval-augmented generation bypasses forgetting by feeding historical data directly into prompts, it introduces significant operational expenses and latency as context windows swell. In contrast, Google researchers reported that their framework preserved past task performance on sequential translation and complex reasoning evaluations while compressing the equivalent of up to 10 million tokens of long-term knowledge directly into model parameters. The architecture relies on an offline dreaming phase that generates synthetic data to reinforce cross-domain associations, tested across lightweight open-weight models including Qwen 1.7B and 8B.
From an operational infrastructure standpoint, the architecture offers a potential structural shift in how enterprises manage agentic artificial intelligence services. By periodically translating conversational logs and context into underlying weights, systems could drastically shorten input prompts during live inference, driving down cumulative token-processing fees. However, Google has not disclosed whether the framework has been integrated into commercial production pipelines, nor has it released detailed breakdowns of the graphics processing unit compute required per offline cycle. Engineering teams evaluating the technology will need to weigh the ongoing infrastructure expenses of running offline distillation cycles against the recurring token costs of live retrieval indices, while researchers continue studying hallucination risks tied to synthetic data accumulation.